The Windows half of this series was about an agent that works on an OS the vendor hasn’t listed. This one is the opposite: a package on a fully supported platform that does nothing, silently, because of a dependency its own documentation doesn’t mention.
The supported route comes first. The rest is the path underneath, as it ran on f06 (VCF 9.1).
The symptom
Install the Telegraf package on a VKS cluster with the metric proxy flag
set (isMetricProxyConfigured: true, which you want when metrics go to
VCF Operations). Every Telegraf pod then stays in ContainerCreating:
NAME           PACKAGE NAME                         PACKAGE VERSION         DESCRIPTION                                                            AGE   PAUSED
...
telegraf       telegraf.kubernetes.vmware.com       1.34.4+vmware.2-vks.1   Reconcile failed: Error (see .status.usefulErrorMessage for details)   15m

kapp: Error: waiting on reconcile deployment/telegraf (apps/v1) namespace: tanzu-system-telegraf:
  Finished waiting unsuccessfully:
    Deployment is not progressing:
      ProgressDeadlineExceeded, message:
        ReplicaSet "telegraf-7cd76f96" has timed out progressing.

NAME                      READY   STATUS              RESTARTS   AGE
telegraf-26ppl            0/1     ContainerCreating   0          15m
telegraf-7cd76f96-wbthp   0/1     ContainerCreating   0          15m
telegraf-g4qlm            0/1     ContainerCreating   0          15m
telegraf-h2pcq            0/1     ContainerCreating   0          15m
Describe one, and the reason is FailedMount: two secrets don’t exist.
...
  Warning  FailedMount  5m14s (x13 over 15m)  kubelet            MountVolume.SetUp failed for volume "metrics-proxy-tls-config" : secret "metrics-proxy-tls-config" not found
  Warning  FailedMount  3m12s (x14 over 15m)  kubelet            MountVolume.SetUp failed for volume "telegraf-configs" : secret "metrics-proxy-http-config" not found
Nothing creates them. The package doesn’t. The cluster doesn’t. The
PackageInstall reports ReconcileFailed and backs off, and there it
stays, waiting for two secrets that aren’t coming.
The supported route first
On VCF 9.1, VKS add-on management installs Telegraf and Prometheus for you. Broadcom’s page on enabling monitoring for VKS clusters (linked at the end) puts it plainly: “After the prerequisites are met, any new VKS cluster is automatically monitored.” It speaks only of new clusters. The prerequisites, and how to check each:
- VCF Operations monitors the vCenter and its Supervisor: Enable vSphere Supervisor Collection in the vCenter account’s Advanced Settings, true by default. Look for a vSphere Supervisor adapter instance and VKS Cluster objects in the inventory.
- The Metrics Aggregator runs on the Supervisor. VCF Automation installs it by default. Check the Supervisor’s services in vCenter.
- The add-on repository offers Telegraf and Prometheus:
AddonRepository,AddonandAddonConfigDefinitionresources on the Supervisor.
On 9.0.1 and later, Tom Fojta’s Monitoring VKS Cluster in VCF
Automation
installs the same two packages as add-on tiles in VCF Automation, once
the provider enables the Supervisor Management Proxy. His notes include a
Telegraf failure over an existing metrics-proxy-tls-config secret: the
mirror image of the one above.
f06 took neither route on 23 August. It ran 9.1, but its VCF Automation arrived the next day. Ops had a vSphere Supervisor adapter instance, the Metrics Aggregator wasn’t registered, and nobody looked for add-ons. By nobody, I mean me. The lab’s catalog item installed the standard package itself, following Christian Ferber’s vrealize.it write-up for 9.0.1. That path is the rest of this post.
Two days later, with VCF Automation deployed and the Supervisor rebuilt, the automatic route left a footprint. A cluster created through VCF Automation’s API had Telegraf and Prometheus namespaces within two minutes, none of it mine:
NAME                     STATUS   ROLES           AGE    VERSION
vks-demo01-jn7xr-2gkq9   Ready    control-plane   111s   v1.35.5+vmware.1
--- namespaces ---
NAME                                 STATUS   AGE
...
tanzu-system-monitoring              Active   18s
tanzu-system-telegraf                Active   11s
...
The rebuilt demo01 had them too, before the catalog item’s package stage ran. So the item’s PackageInstalls collided with another kapp app:
=== telegraf ===
kapp: Error: Ownership errors: - Resource 'clusterrole/telegraf-kubelet-metric-access (rbac.authorization.k8s.io/v1) cluster' is already associated with a different label 'kapp.k14s.io/app=1787648814041772277' - Resource 'serviceaccount/telegraf-sa (v1) namespace: tanzu-system-telegraf' is already a
...
I didn’t inspect what installed them (the Supervisor was serving the
addons.kubernetes.vmware.com API by then). It’s a footprint, not a
test. Check for Telegraf before you install it.
What sits underneath
The two secrets come from the Supervisor Management Proxy, a Supervisor Service on the Supervisor, not in the guest. It runs envoy behind a load balancer on port 10093.
Each guest cluster gets a headless Service pointing at it
(supervisor-management-proxy in default), plus the two secrets in
kube-system, each with a SecretExport. The package’s SecretImports
copy them into tanzu-system-telegraf, and Telegraf posts to
https://supervisor-management-proxy.default.svc.<serviceDomain>:10093/arc/tkgs/metric.
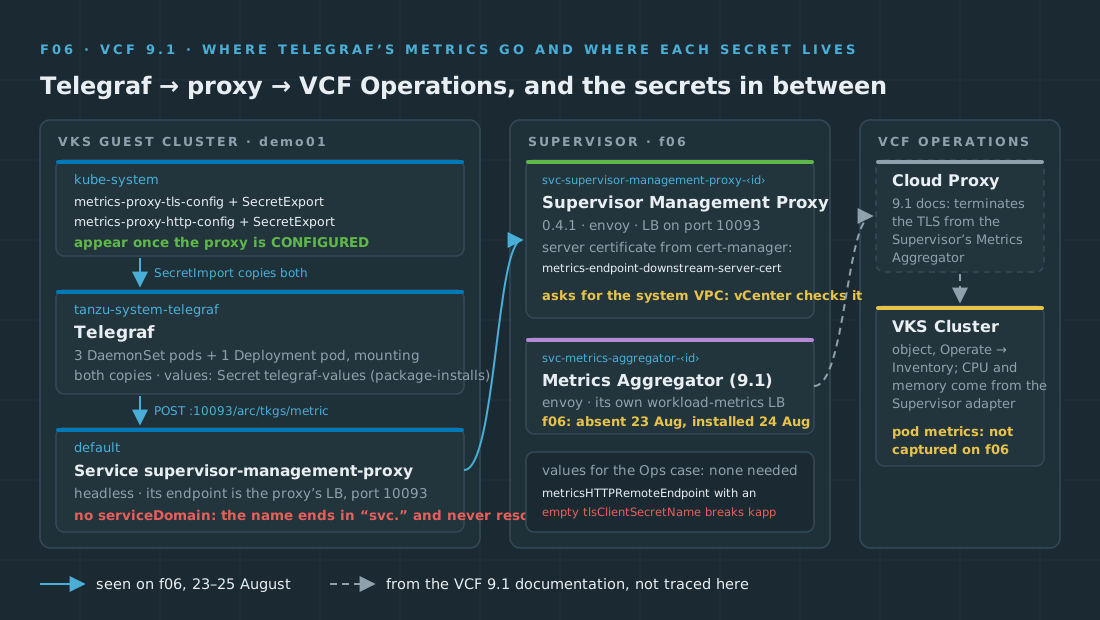 Solid: what f06 showed. Dashed: the 9.1 design, in which the Supervisor also issues Telegraf’s certificates and cert-manager rotates them.
The manual path needs a Supervisor with a load balancer, registry access
to projects.packages.broadcom.com, vCenter rights to register
Supervisor Services, and cluster-admin in the guest. The cluster is
demo01: one control-plane node and two workers.
1. Install the Supervisor Management Proxy
The lab’s catalog item that deploys a Supervisor has an
installMgmtProxy tick box: register the service, then install it.
Every attempt was refused. The definition shows why:
apiVersion: data.packaging.carvel.dev/v1alpha1
kind: Package
metadata:
  name: supervisor-management-proxy.vmware.com.0.4.1
  annotations:
    appplatform.vmware.com/use-system-vpc: "true"
    appplatform.vmware.com/required_capability: Load_Balancer_Supported
    appplatform.vmware.com/vcenter-version-constraints: '>=9.0.0'
spec:
  refName: supervisor-management-proxy.vmware.com
  version: 0.4.1
The proxy asks for the system VPC. vCenter only places services there that it can verify as published by Broadcom:
=== install on supervisor domain-c9 ===
  install failed: 500
...
      "default_message": "Service supervisor-management-proxy.vmware.com version 0.4.1 is not a trusted service published by Broadcom and cannot be placed on the system VPC.",
      "id": "vcenter.wcp.appplatform.signature_verification.system_vpc"
...
Registered through the API as Carvel YAML, it never passed, even byte-identical to Broadcom’s download. The other Carvel services here carry no such annotation and installed fine:
harbor                       2.14.2+vmware.2-vks.2    no system-vpc annotation  content_type=CARVEL_APPS_YAML
cci-ns                       9.1.0-embedded+739b5075  no system-vpc annotation  content_type=CARVEL_APPS_YAML
velero                       1.9.0-embedded+25369333  no system-vpc annotation  content_type=CARVEL_APPS_YAML
That check is doing its job, and I won’t show how the lab got past it. On a platform you care about, install the proxy the way Broadcom’s proxy page (linked at the end) describes, so vCenter can verify what it places on the system VPC. However it goes in, check it on the Supervisor:
  [30s] service=CONFIGURED  pod=Running ready=1/1
--- LB services in proxy ns ---
  workload-metrics-loadbalancer: type=LoadBalancer ip=10.26.20.21 ports=10093
...
Then check it in vCenter. The install record holds only the namespace the
platform chose (the base64 is namespace: svc-supervisor-management-proxy-acqyd):
--- current install record ---
{
  "desired_version": "0.4.1",
  "current_version": "0.4.1",
...
        "default_message": "Reason: ReconcileSucceeded. Message: Reconcile succeeded.",
...
  "yaml_service_config": "bmFtZXNwYWNlOiBzdmMtc3VwZXJ2aXNvci1tYW5hZ2VtZW50LXByb3h5LWFjcXlkCg==",
  "service_namespace": "svc-supervisor-management-proxy-acqyd",
  "display_name": "Supervisor Management Proxy",
  "config_status": "CONFIGURED"
}
2. Create the cluster with serviceDomain
clusterNetwork.serviceDomain can’t be added later (step 7). The catalog
item now sets it on every demo cluster. Here’s demo01 as rebuilt:
{
  "clusterNetwork": {
    "pods": {
      "cidrBlocks": [
        "192.168.0.0/16"
      ]
    },
    "serviceDomain": "cluster.local",
    "services": {
      "cidrBlocks": [
        "10.96.0.0/12"
      ]
    }
  },
...
3. Add the package repository
Telegraf ships in Broadcom’s VKS standard packages. Register the
repository in the guest’s tkg-system namespace:
apiVersion: packaging.carvel.dev/v1alpha1
kind: PackageRepository
metadata:
  name: broadcom-standard-repo
  namespace: tkg-system
spec:
  fetch:
    imgpkgBundle:
      image: projects.packages.broadcom.com/vsphere/supervisor/packages/2025.8.19/vks-standard-packages:v2025.8.19
packagerepository.packaging.carvel.dev/broadcom-standard-repo created

NAME                     AGE   DESCRIPTION           PAUSED
broadcom-standard-repo   60s   Reconcile succeeded

=== packages available ===

NAME                                                                  PACKAGEMETADATA NAME                             VERSION                  AGE
...
telegraf.kubernetes.vmware.com.1.34.4+vmware.2-vks.1                  telegraf.kubernetes.vmware.com                   1.34.4+vmware.2-vks.1    54s
telegraf.tanzu.vmware.com.1.32.1+vmware.1-tkg.1                       telegraf.tanzu.vmware.com                        1.32.1+vmware.1-tkg.1    54s
4. Install Telegraf
Two values matter, from the package’s own schema:
--- telegraf package valuesSchema keys ---
...
  domainName  (default: cluster.local)
...
  isMetricProxyConfigured  (default: False)
  namespace  (default: tanzu-system-telegraf)
...
The catalog item installs it the Carvel way: a values Secret, then a
PackageInstall, in a package-installs namespace whose service account
has cluster-admin.
    function pkgSecret(name, valuesYml) {
        k8sApply(gk, gTok, "/api/v1/namespaces/package-installs/secrets", {
            apiVersion: "v1", kind: "Secret",
            metadata: { name: name, namespace: "package-installs" },
            stringData: { "values.yml": valuesYml } }, "secret " + name);
    }
    function pkgInstall(name, refName, ver, valuesSecret) {
        ...
        var pi = { apiVersion: "packaging.carvel.dev/v1alpha1",
            kind: "PackageInstall",
            metadata: { name: name, namespace: "package-installs" },
            spec: { serviceAccountName: "pkgi-sa",
                ...
                packageRef: { refName: refName,
                    versionSelection: { constraints: ver } } } };
        if (valuesSecret) { pi.spec.values = [{ secretRef: { name: valuesSecret } }]; }
        ...
    }
    ...
    pkgSecret("telegraf-values",
        "domainName: cluster.local\n" +
        "isMetricProxyConfigured: true\n");
    pkgInstall("telegraf", "telegraf.kubernetes.vmware.com",
        "1.34.4+vmware.2-vks.1", "telegraf-values");
The pods land in tanzu-system-telegraf: one per node from a DaemonSet,
plus one Deployment pod.
5. Watch the secrets arrive
This is the dependency. Within two minutes of the proxy reporting
CONFIGURED, the secrets and their SecretExports were in demo01’s
kube-system. The SecretImports had copied them across:
--- secrets + secretimports in tanzu-system-telegraf ---
  secrets: metrics-proxy-http-config, metrics-proxy-tls-config, telegraf-registry-creds
  secretimport: metrics-proxy-http-config -> ReconcileSucceeded=True
  secretimport: metrics-proxy-tls-config -> ReconcileSucceeded=True
  kube-system secretexport: metrics-proxy-http-config toNamespaces=
  kube-system secretexport: metrics-proxy-tls-config toNamespaces=
...
The pods came up on their own:
  [30s] telegraf pods ready: 0/4  pkgi: ReconcileFailed=True
  [60s] telegraf pods ready: 2/4  pkgi: ReconcileFailed=True
  [90s] telegraf pods ready: 4/4  pkgi: ReconcileFailed=True
...
  [480s] telegraf pods ready: 4/4  pkgi: ReconcileFailed=True
After an hour and forty minutes of FailedMount, all four were Running
four minutes after the proxy went CONFIGURED. I’d quite like that hour
and forty minutes back.
6. Clear the stale backoff
The PackageInstall stayed in its ReconcileFailed backoff with every pod
Running. Bumping an annotation forces a fresh reconcile:
$K=@{Authorization="Bearer $($lg.session_id)"; 'Content-Type'='application/merge-patch+json'}
...
$u="https://${gk}:6443/apis/packaging.carvel.dev/v1alpha1/namespaces/package-installs/packageinstalls/telegraf"
...
# force re-reconcile by bumping an annotation
$patch='{"metadata":{"annotations":{"lab.kick":"'+(Get-Random)+'"}}}'
Invoke-RestMethod -Method Patch -Uri $u -Headers $K -Body $patch -SkipCertificateCheck | Out-Null
...
kicked; polling...
  [30s] ReconcileSucceeded=True Reconcile succeeded
7. Check the output URL
Telegraf still wasn’t delivering. Its log, one error a minute:
  2026-08-23T19:17:56Z I! [agent] Config: Interval:5m0s, Quiet:false, Hostname:"telegraf-7cd76f96-wbthp", Flush Interval:1m0s
...
  2026-08-23T19:20:03Z E! [agent] Error writing to outputs.http: Post "https://supervisor-management-proxy.default.svc.:10093/arc/tkgs/metric": dial tcp: lookup supervisor-management-proxy.default.svc. on 10.96.0.10:53: no such host
  2026-08-23T19:20:56Z E! [agent] Error writing to outputs.http: Post "https://supervisor-management-proxy.default.svc.:10093/arc/tkgs/metric": dial tcp: lookup supervisor-management-proxy.default.svc. on 10.96.0.10:53: no such host
...
Note the trailing dot, and nothing after svc. The name is that headless
Service:
--- guest 'default' ns services ---
  kubernetes: type=ClusterIP extName= clusterIP=10.96.0.1
  supervisor: type=ClusterIP extName= clusterIP=None
  supervisor-management-proxy: type=ClusterIP extName= clusterIP=None
...
--- endpoints of supervisor-management-proxy (default ns) ---
  ips=10.26.20.21 ports=10093
The domain part follows the cluster’s serviceDomain, which demo01
lacked. The package’s own domainName was cluster.local all along, and
made no difference. Adding the field later was refused:
patch rejected:  { "kind": "Status", "apiVersion": "v1", "metadata": {}, "status": "Failure", "message": "admission webhook \u0022capi.validating.tanzukubernetescluster.run.tanzu.vmware.com\u0022 denied the request: spec.clusterNetwork is immutable and cannot be upd
...
Two fixes, both applied:
- Every new cluster:
serviceDomain: cluster.localin the spec (step 2). Every add-on that builds a service URL assumes it’s there. - Live cluster: a CoreDNS
rewriterule in the guest’scorednsConfigMap, mapping the domainless name onto the real one. Ugly, effective, and documented in the cluster’s notes. Thereloadplugin picked it up:
--- Corefile now ---
.:53 {
    errors
    health {
       lameduck 5s
    }
    ready
    rewrite name supervisor-management-proxy.default.svc supervisor-management-proxy.default.svc.cluster.local
    kubernetes cluster.local in-addr.arpa ip6.arpa {
...
8. Leave the proxy’s values alone
The error moved on, which counts as progress around here. The name resolves now, and nothing answers:
checked at (UTC): 19:35:38
telegraf-26ppl: STILL FAILING (4 errors)
  last: 2026-08-23T19:35:07Z E! [agent] Error writing to outputs.http: Post "https://supervisor-management-proxy.default.svc.:10093/arc/tkgs/metric": context deadline exceeded (Client.Timeout exceeded while awaiting headers)
...
In 9.1 terms, a prerequisite was missing. The Metrics Aggregator, which terminates the cluster’s TLS in that design, didn’t exist on f06 yet. I tried pointing the proxy at Ops by hand, with a value from its definition:
        metricsHTTPRemoteEndpoint:
          title: HTTP remote endpoint configuration for pushing workload metrics
          ...
          properties:
            host:
              ...
            port:
              ...
              default: 443
              ...
            tlsClientSecretName:
              type: string
              description: Name of the secret which contains the TLS configuration required to push metrics to remote endpoint.
              default: ""
            tlsClientSecretNamespace:
              ...
              default: "vmware-system-monitoring"
A PUT on the install record (PATCH returns 404) reconciled:
$vals="namespace: svc-supervisor-management-proxy-acqyd`nmetricsHTTPRemoteEndpoint:`n  host: `"f06-flt-ops01.res.lab`"`n  port: 443`n"
$b64=[Convert]::ToBase64String([Text.Encoding]::UTF8.GetBytes($vals))
$body=@{ version='0.4.1'; yaml_service_config=$b64 } | ConvertTo-Json
...
  $r=Invoke-WebRequest -Method Put -Uri "https://$vc/api/vcenter/namespace-management/clusters/domain-c9/supervisor-services/$svc" -Headers $H -ContentType 'application/json' -Body $body -SkipCertificateCheck -TimeoutSec 120
PUT -> 204
  [30s] CONFIGURED
  [60s] CONFIGURED
  [90s] CONFIGURED
Telegraf timed out as before. Broadcom’s proxy page is blunt: “No additional configuration values for the Supervisor Management Proxy service are required in this case.”
Set at install time, the value did harm. With no tlsClientSecretName,
the package renders a nameless SecretImport, and kapp refuses it:
=== supervisor-management-proxy.vmware.com ===
Reason: ReconcileFailed. Message: kapp: Error: Validation errors:
- Expected 'metadata.name' on resource 'secretimport/ (secretgen.carvel.dev/v1alpha1) namespace: svc-supervisor-management-proxy-htarg' to be non-empty (stdin doc 5).
The next day, the Supervisor was rebuilt onto the lab’s planned address
range. The catalog item installed the proxy and the Metrics Aggregator
with no values, and both went CONFIGURED:
--- ALL LoadBalancer VIPs on the rebuilt supervisor ---
...
  svc-metrics-aggregator-5q0of             workload-metrics-loadbalancer 192.168.144.7
  svc-supervisor-management-proxy-htarg    workload-metrics-loadbalancer 192.168.144.6
demo01 was recreated on that Supervisor with serviceDomain set. This
check read a Telegraf pod’s last two minutes of log. The broken state had
logged an error a minute:
=== observability packages ===
  cert-manager   ReconcileSucceeded=True
  contour        Reconciling=True
  fluent-bit     ReconcileSucceeded=True
  prometheus     ReconcileFailed=True
  telegraf       ReconcileFailed=True
=== telegraf delivery (last 2 min) ===
  CLEAN - metrics flowing to mgmt proxy
“Metrics flowing” is my script’s wording for no failed writes. And the
telegraf PackageInstall is the one kapp refused, so the clean Telegraf
wasn’t mine.
9. VCF Operations
Broadcom’s consumption docs show the result in VCF Automation (Manage and Govern > Kubernetes Management > Clusters) and in a Workload Management Activated Cluster Summary tab in VCF Operations. The 9.0.1 write-up adds a switch on the VKS Cluster object, which the catalog item still names at the end of each run:
... | Ops manual step: set 'Pod And Container Monitoring Enabled' on VKS Cluster demo01 in VCF Operations inventory; ...
This record has neither. The switch was never set, and my one capture of a VKS Cluster object (vks-demo01, 1 September, in the two-ways post) counts 0 pods, deployments and DaemonSets. The last hop I can show is Telegraf writing without errors. Not the grand finale I’d hoped for, but an honest one.
Clean-up and repeatability
- One owner per add-on. Where add-on management installs Telegraf,
don’t add your own PackageInstall. To run it yourself, first set the
cluster label
addons.kubernetes.vmware.com/automated-monitoringtodisabled. The catalog item’s answer to the ownership errors,--dangerous-override-ownership-of-existing-resources=true, only hands the objects to a second owner. - Supervisor Service API on 9.1: service
carvel_spec.version_spec.content, versioncarvel_spec.content, install{supervisor_service, version}, valuesPUT {version, yaml_service_config}, removalPATCH …?action=deactivate, thenDELETE. New definition bytes need a new service record. - A definition outlives the Supervisor. What you register lives on vCenter’s service record, so a rebuilt Supervisor installs the same definition again. Replacing it means deactivating and deleting that record first.
- Services break later. In September, the proxy, the aggregator and
four other Supervisor Services went to
ERRORwhen the platform replaced their kapp service accounts. Recreating the old ones fixed all six within two minutes.
Why this matters outside the lab
On VCF 9.1, Kubernetes metrics in VCF Operations are meant to be a platform setting, not a job per cluster. Get three prerequisites right, and new clusters arrive monitored.
The layer underneath still matters, because every failure here had the
same shape: a generic symptom (FailedMount, a name that won’t resolve,
a timeout) caused by a decision made somewhere else.
For a customer, that means a Supervisor built for observability before any cluster asks, a cluster baseline with the fields add-ons assume, and one owner per add-on. That’s exactly what a standard cluster class and a Supervisor build checklist exist to encode.
Rules learned
- On 9.1, start with the supported route: Ops collecting the Supervisor, the Metrics Aggregator and the add-on repository. Then check for Telegraf before installing it.
- On VKS, the Telegraf package hard-depends on the Supervisor
Management Proxy whenever the metric proxy flag is set.
FailedMounton twometrics-proxy-*secrets is the tell. - The dependency heals retroactively: install the proxy, bump the PackageInstall annotation, wait.
- Set
serviceDomainat cluster create. It’s immutable, and every add-on that builds a service URL will assume it. - A name that resolves isn’t a metric delivered. Read the output log for an error-free window, and leave the proxy’s values alone.
- When a package “does nothing”, describe the pod, not the package.
Broadcom documentation
- Enabling Monitoring for VKS Clusters: the 9.1 route and its prerequisites.
- Enabling Monitoring for vSphere Supervisor: the Supervisor collection setting on the vCenter account.
- Monitoring VKS Clusters Using VCF Operations: the automated add-ons, the metrics-aggregator service, and where metrics appear.
- Disable Automated Monitoring on VKS Clusters Using VCF Automation: the per-cluster label, for clusters where you run Telegraf yourself.
- Using the Supervisor Management Proxy Service: what the proxy is for; no extra values for VCF Operations.
Previously: Telegraf on Windows Server 2025. More in the Observability on VCF series.
Lab environment; opinions my own.